1Soongsil University 2Seoul National University
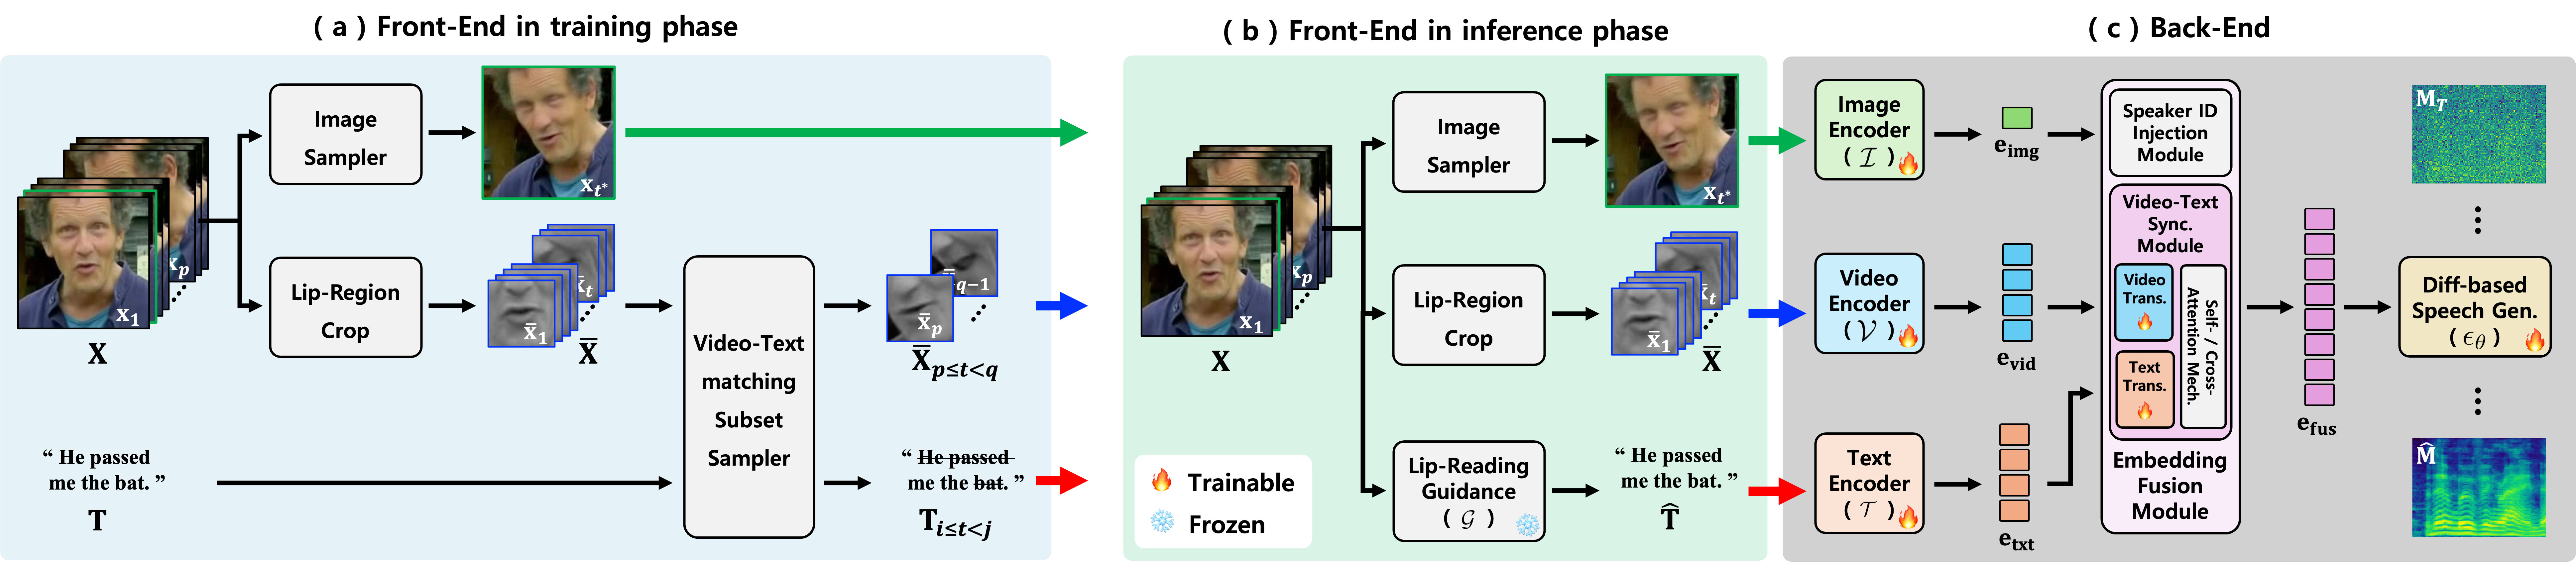
Video-to-speech synthesis aims to generate natural-sounding speech from silent talking-face videos while ensuring phonetic accuracy. A fundamental challenge in this task is the inherent one-to-many mapping problem, where visual dynamics often lack sufficient information to uniquely determine the corresponding utterance. To address this, we propose Watch Your Speech (WYS), a video-to-speech synthesis framework that incorporates textual conditioning as an explicit linguistic cue to mitigate visual ambiguity. Our framework features an attention-based embedding fusion module that synergistically integrates textual context with video sequences, coupled with a conditional flow matching objective for high-fidelity speech generation. Extensive experiments on the LRS2 and LRS3 datasets demonstrate that WYS achieves superior performance, establishing new state-of-the-art results in audio-visual synchronization (LSE-C/D) while maintaining highly competitive textual accuracy (WER). Subjective evaluations further confirm that our model generates speech with near-human naturalness, validating the effectiveness of textual conditioning in content-controlled video-to-speech synthesis.
| Silent video | Ground Truth | VCA-GAN [1] | SVTS [2] | DiffV2S [3] | IntelligibleL2S [4] | LipVoicer [5] | V2SFlow-A [6] | V2SFlow-V [6] | Proposed | Text |
|---|---|---|---|---|---|---|---|---|---|---|
| I love building robots | ||||||||||
| We can't see it most of the time | ||||||||||
| I mean how do they form | ||||||||||
| I tried everything | ||||||||||
| There were no back doors | ||||||||||
| But it's a global phenomenon |
| Silent video | Ground Truth | VCA-GAN [1] | DiffV2S [3] | IntelligibleL2S [4] | LipVoicer [5] | V2SFlow-A [6] | V2SFlow-V [6] | Proposed | Text |
|---|---|---|---|---|---|---|---|---|---|
| It would have been Completely alien to the rest of london | |||||||||
| So to do ballroom | |||||||||
| And we were right | |||||||||
| Some burn brightly for a year or two | |||||||||
| That is a first | |||||||||
| Something like a garden compost |
[1] VCA-GAN: Lip to Speech Synthesis with Visual Context Attentional GAN
[2] SVTS: SVTS: Scalable Video-to-Speech Synthesis
[3] DiffV2S: DiffV2S: Diffusion-based Video-to-Speech Synthesis with Vision-guided Speaker Embedding
[4] IntelligibleL2S: Intelligible Lip-to-Speech Synthesis with Speech Units
[5] LipVoicer: LipVoicer: Generating Speech from Silent Videos Guided by Lip Reading
[6] V2SFlow: V2SFlow: Video-to-Speech Generation with Speech Decomposition and Rectified Flow